Scientific Anomaly Detection in Public Media
Billions of photos and videos are uploaded every day for completely ordinary reasons, but their backgrounds can accidentally capture rare species, environmental changes, disease patterns, geological features, or other scientifically valuable evidence that nobody notices. Build a discovery system that continuously scans public media, identifies unusual objects or conditions, compares them with what science believes should exist in that place and time, and routes high-value anomalies to the right researchers with the image, location, date, and supporting evidence. This matters now because computer vision can analyze media at enormous scale while smartphones have effectively created a global network of unintentional scientific sensors. Imagine a tourist posting a beach selfie and the system discovering a coral species hundreds of miles outside its known range in the background.
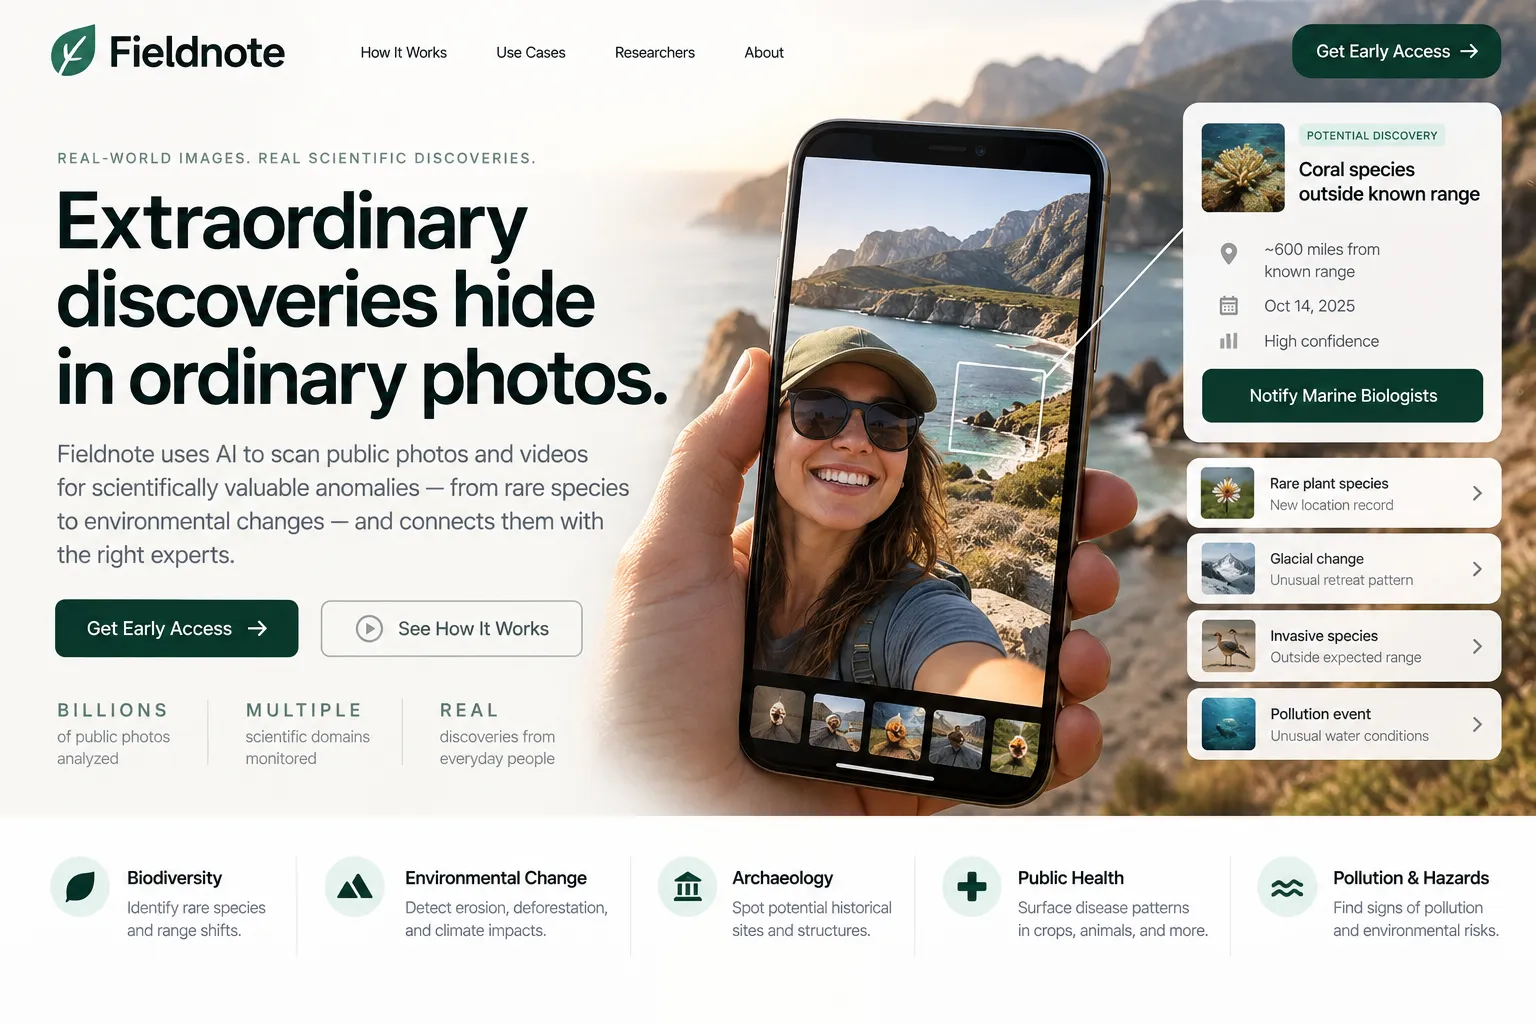
Description
No additional description provided.
The Pitch
This turns the internet’s lowest-intent data into one of the world’s richest scientific observation networks. Most citizen-science systems depend on someone deciding that a bird, plant, insect, lesion, rock formation, water color, or shoreline change is worth documenting. But many of the most valuable observations are captured by people who have no idea they saw anything important. The overlooked background is the interesting asset: it is less curated, less biased toward charismatic subjects, and orders of magnitude larger than deliberate submissions.
The defensibility would come less from image recognition alone than from building a living map of “what should be here.” An isolated photo of a plant, animal, fungus, algae bloom, landslide, crop disease, or coastal condition is not automatically meaningful. It becomes meaningful when compared against expected ranges, seasons, migration patterns, land-use history, weather, prior observations, and scientific uncertainty. The company that learns to rank surprise well would sit between raw media and research-grade evidence, which is a much harder position to copy than a generic visual search tool.
Its value would also compound because science has a verification bottleneck, not just a data bottleneck. Researchers do not need a firehose of possible anomalies; they need a small number of well-supported leads with enough context to justify attention. If the system becomes trusted at triaging evidence—separating the merely strange-looking from the genuinely unlikely—it can save specialists from scanning noise while still surfacing events they would otherwise never see. In fields where a single early detection can matter, such as invasive species, crop pathogens, coral bleaching, wildlife disease, or habitat loss, timeliness is often worth more than completeness.
The deeper business insight is that many institutions already spend heavily to observe the world, but their instruments are sparse, expensive, and pointed at known concerns. Meanwhile, public media forms a dense, accidental sensor layer over places formal monitoring rarely reaches: vacation beaches, hiking trails, farms, backyards, roadsides, markets, and disaster zones. The company would not replace satellites, fieldwork, or lab science; it would add a missing layer of ground-level serendipity, where the cost of collection has already been paid by billions of ordinary people doing ordinary things.
If it worked, it could create a new category of scientific infrastructure: not a social network for discovery, but a quiet translation layer between human attention and machine attention. The world is already being photographed continuously. The business exists in noticing what the photographers did not.